Opus 5.5 and Fable 5.2
Is Opus 5.5 nerfed after Fable 5.2's release?
A theory goes around online that Anthropic's older models get worse whenever a new one is released. Some Bench happened to run Opus 5.5 before and after one release, Fable 5.2, with the same tests and the same settings, so here is what that showed.
At high effort, Opus 5.5 got shorter and slightly worse. At low and medium effort, nothing moved beyond the usual run-to-run variation. One release and one run after it can't confirm the theory, but the high-effort change is the largest token drop in our data.
The runs
Fable 5.2 came out on 10 November, and the third run of Opus 5.5 is from that day.
| Opus 5.5 | 24 Sep | 22 Oct | 10 Nov, Fable 5.2 release day |
|---|---|---|---|
| High: score | 71.4% | 71.4% | 68.0% |
| High: harder variant, exact | 56.1% | 55.0% | 50.0% |
| High: completion tokens per task | 614 | 656 | 552 (−16%) |
| High: seconds per task | 9.2 | 9.8 | 7.5 |
| High: cost per test | $0.0200 | $0.0179 | $0.0139 |
| Medium: score | 68.9% | 66.6% | 68.3% |
| Medium: completion tokens per task | 506 | 499 | 472 |
| Low: score | 65.0% | 65.3% | 65.0% |
| Low: completion tokens per task | 318 | 324 | 319 |
At high effort the model wrote 16% fewer completion tokens (which include its reasoning), answered 23% faster, cost 22% less per test and lost 3.4 points, almost all of them on the harder variant. That looks like less thinking per answer, not a different model: low effort, which thinks least, didn't change at all.
Is that more than noise?
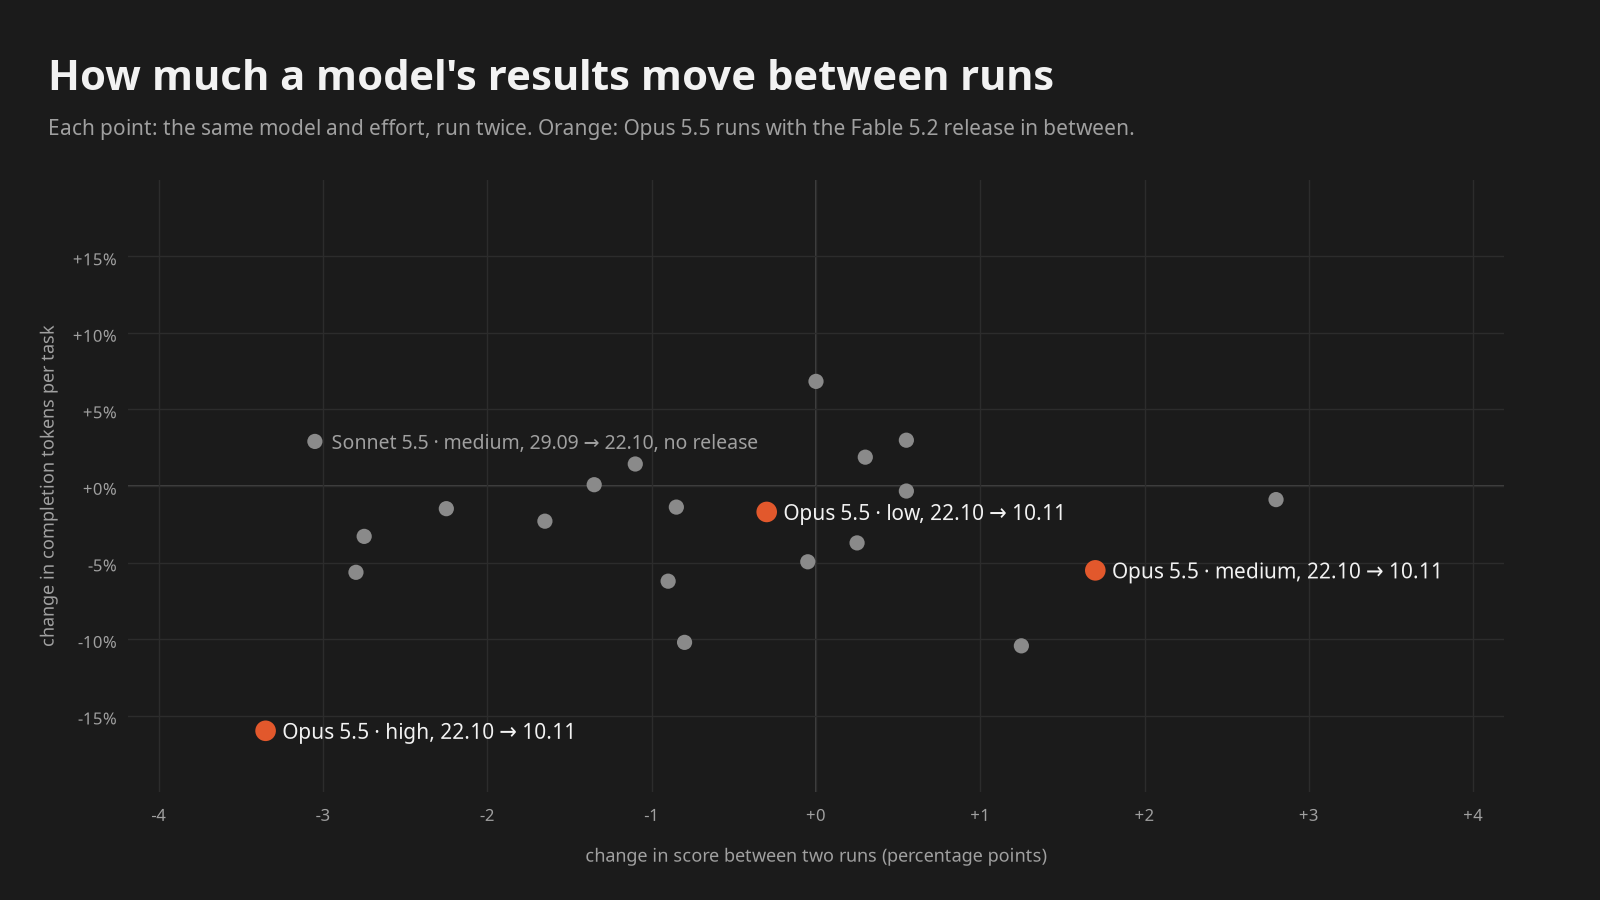
Running the same model twice never gives exactly the same result. Every model we ran more than once is on the chart, so the orange points can be compared with the normal spread in grey:
- Score: a 3.4-point drop is the largest in our data, but only just. Sonnet 5.5 at medium effort dropped 3.0 points between 29 September and 22 October, with no release in between.
- Tokens: a 16% drop stands out more clearly. Every other pair of runs stayed within 7%.
What this doesn't show
- One event. To test "older models get worse at each release", the same check has to hold across several releases, not one.
- No comparison run after the release. Only Opus 5.5 was run again on 10 November. Running Sonnet 5.5, Fable 5.1 and a model from another company on the same day would show whether something changed for everyone, such as load on the provider's side.
- Why it changed. From outside we can only see that the model writes less and scores lower at high effort. Whether that's a deliberate change, a different thinking budget or a side effect of serving a new model, the numbers can't tell.
We'll run Opus 5.5 at high effort again to see whether the drop holds, and repeat this check at the next Anthropic release.